TinyML brings machine learning to microcontrollers—devices with kilobytes of memory, no operating system in many cases, and power budgets measured in milliwatts. For an embedded engineer starting a TinyML project, the first practical fork in the road is the development framework, and the choice comes down to one central trade-off: a low-level library such as TensorFlow Lite Micro (TFLM) offers greater flexibility and system-level control, while an end-to-end platform such as Edge Impulse provides a more streamlined workflow with automated optimization. An IEEE conference paper comparing the two frameworks directly highlights this divide, concluding that framework selection should rest on whether usability or optimization is the project's priority.
The Typical TinyML Development Workflow
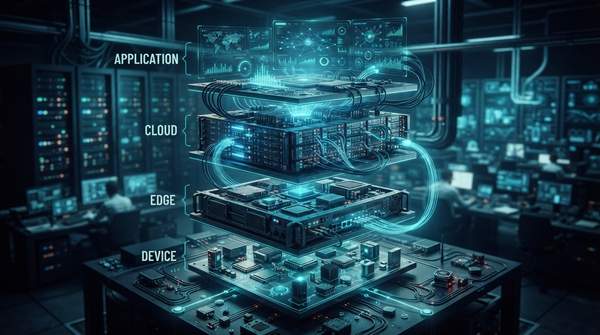
Regardless of which framework a team adopts, the fundamental stages of a TinyML project stay consistent—what varies is the tooling and level of automation at each stage. The pipeline begins with data acquisition: raw signals from sensors are collected, then preprocessed and passed to an optimized machine learning model that has been deployed on the microcontroller. On the device itself, an inference engine executes the model and generates predictions in real time.
The work does not end at prediction. A decision layer converts those predictions into concrete actions—activating a motor, raising an alert, gating a measurement—while optional cloud communication can be reserved for monitoring and management. This layered architecture is what allows intelligent, low-power, real-time machine learning to run directly on embedded devices rather than depending on a round trip to a remote server.
The deployment side is shaped by the harsh realities of microcontroller hardware. Initial TinyML efforts focused on running algorithms natively on stock MCU hardware, but as practitioners in the field have described, the limited on-chip memory—on the order of kilobytes—combined with often non-existent off-chip memory made this challenging and drove research into efficient model design. TinyML systems sometimes run atop lightweight real-time operating systems such as FreeRTOS, but given the tight constraints, applications are frequently deployed bare metal, with no OS at all.
Overcoming Constraints: Challenges and Optimization Techniques in TinyML
The reason a specialized toolkit is needed at all is that microcontrollers invert every assumption of conventional machine learning. Cloud-based ML tolerates large models, abundant RAM, and continuous connectivity; a microcontroller offers none of these. By shifting intelligence from centralized cloud infrastructure to the device level, TinyML addresses the critical challenges associated with latency, bandwidth consumption, energy usage, privacy, and continuous internet dependency—but only if the model can actually fit and run within the device's constraints.
That fitting is the work of model optimization, and it is the technical heart of the field. Techniques documented across the TinyML literature include model compression, quantization, pruning, and hardware-aware deployment, which together enable efficient execution of machine learning models within highly constrained environments. Quantization reduces the numerical precision of model weights and operations; pruning removes redundant parameters; compression and hardware-aware deployment tailor the remaining model to the target chip. The practical effect is that the same network that would be unremarkable on a server becomes viable in kilobytes of memory.
Frameworks themselves must also be engineered for the target class of hardware. As the SIGARCH community's practitioner-oriented discussion of TinyML notes, TinyML frameworks must be portable—seamlessly compiling and running across various architectures—while still providing an easy path to optimize code for platform-specific features in order to meet stringent compute latency requirements. TFLM illustrates one point on this spectrum: it is an inference interpreter that works across various hardware targets with little overhead. Where applications are severely constrained, that overhead can be avoided via compiled runtimes such as microTVM, tinyEngine, STM32CubeAI, and CMSIS-NN—but this comes at the cost of portability. In other words, even the choice of runtime is itself a control-versus-convenience decision, mirroring the framework trade-off at a lower level.
TinyML Framework Comparison: TFLM vs. Edge Impulse
The comparison below classifies the two frameworks against the decision criteria that matter most to an embedded team: how the workflow feels day to day, how much control the developer retains, how optimization is handled, and what kind of project each suits best. The characteristics are drawn from the IEEE framework assessment, which evaluated TFLM and Edge Impulse in the context of low-power microcontrollers and found that TFLM offers greater flexibility and system-level control, whereas Edge Impulse provides a more streamlined workflow with automated optimization.
| Decision criterion | TensorFlow Lite Micro (TFLM) | Edge Impulse (EI) |
|---|---|---|
| Workflow & ease of use | A more flexible, low-level approach that requires manual integration into the embedded system—more development effort, more developer control. | A streamlined, end-to-end platform that simplifies the development process, especially for rapid prototyping. |
| Flexibility & control | Greater flexibility and system-level control over the model and hardware integration—beneficial for projects requiring deep customization or specific hardware optimizations. | A more managed environment that abstracts low-level details; this may offer less granular control compared to TFLM. |
| Optimization features | Supports lightweight inference techniques such as quantization and pruning to reduce model size and computational complexity, applied under the developer's direction. | Automated optimization is built into the workflow, automating some of the complexity of model optimization. |
| Ideal use case | Highly optimized, custom deployments with stringent resource constraints or unique hardware requirements. | Quick prototyping and projects where development speed is critical and an integrated, automated workflow is valued. |
Read across the rows, the table resolves into a single pattern: every dimension where TFLM demands more of the developer is the same dimension where it returns more control, and every dimension where Edge Impulse removes effort is the same dimension where it narrows the developer's options. Neither row is superior in the abstract—the assessment's own framing is that the findings support informed framework selection based on usability or optimization priorities.
Choosing the Right Framework for Your Embedded ML Project
Turning the comparison into a decision means asking which constraint actually binds your project. If the binding constraint is the device—kilobytes of on-chip memory, a bare-metal deployment, unusual silicon, latency requirements that force you toward compiled runtimes—then TFLM's low-level approach is the natural fit, because those projects require the deep customization and fine-grained hardware integration that a managed platform would abstract away. The cost is upfront: manual integration of the interpreter into your embedded system, and optimization work that stays in your hands.
If the binding constraint is time—a proof of concept due in weeks, a small team without a dedicated ML engineer, a product where the microcontroller is adequate and the question is how quickly intelligence can be added—then Edge Impulse's integrated path is the better alignment. Its automated optimization removes work that would otherwise consume the schedule, at the price of less granular control than TFLM affords.
It is also worth remembering that these are representative examples, not the whole landscape: the field includes compiled alternatives such as microTVM, tinyEngine, STM32CubeAI, and CMSIS-NN for severely constrained applications, and the IEEE assessment situates TFLM and Edge Impulse within a broader ecosystem that also includes general-purpose frameworks like TensorFlow, PyTorch, and Scikit-learn. The comparison here reflects the characteristics and intended use cases described in that published assessment, not hands-on performance benchmarks of the two tools.
Making Your TinyML Framework Decision
The decision, stated plainly: choose TensorFlow Lite Micro for projects demanding maximum system-level control, deep customization, and fine-grained optimization, or opt for Edge Impulse when prioritizing rapid development, an integrated workflow, and automated model deployment. The measurable indicator that will tell you whether the choice was right is the project's development velocity and the degree of hardware-software integration achieved. If Edge Impulse was the correct call, that shows up as a working prototype moving quickly through the data-to-deployment loop; if TFLM was correct, it shows up as a model squeezed into the memory and latency envelope that a streamlined platform could not have hit on its own. Track which of those two outcomes your project actually needs before committing the codebase.
Sources
- IEEE Xplore Full-Text PDF: — Ieeexplore
- TinyML: Why the Future of Machine Learning is Tiny and Bright — SIGARCH